WebGPU is here
WebGPU is here. Pages can now use a modern graphics and compute API, drawn and computed on the real GPU, with the official conformance suite passing 96.1% of the cases it ran and the four public samples we tried running live. A test cube matches the reference browser on every pixel we compared. It is built to give a site less than the reference does: one identity for every machine, no GPU clock, and memory charged before it is allocated. Running that suite also found crashes a page could cause, and those are fixed here too. This release also closes a serious privacy hole: until now a page could read back the pixels of an image from another site through a canvas. The GPU row moves 65 to 75 and the overall score 74 to 75.
WebGPU, measured
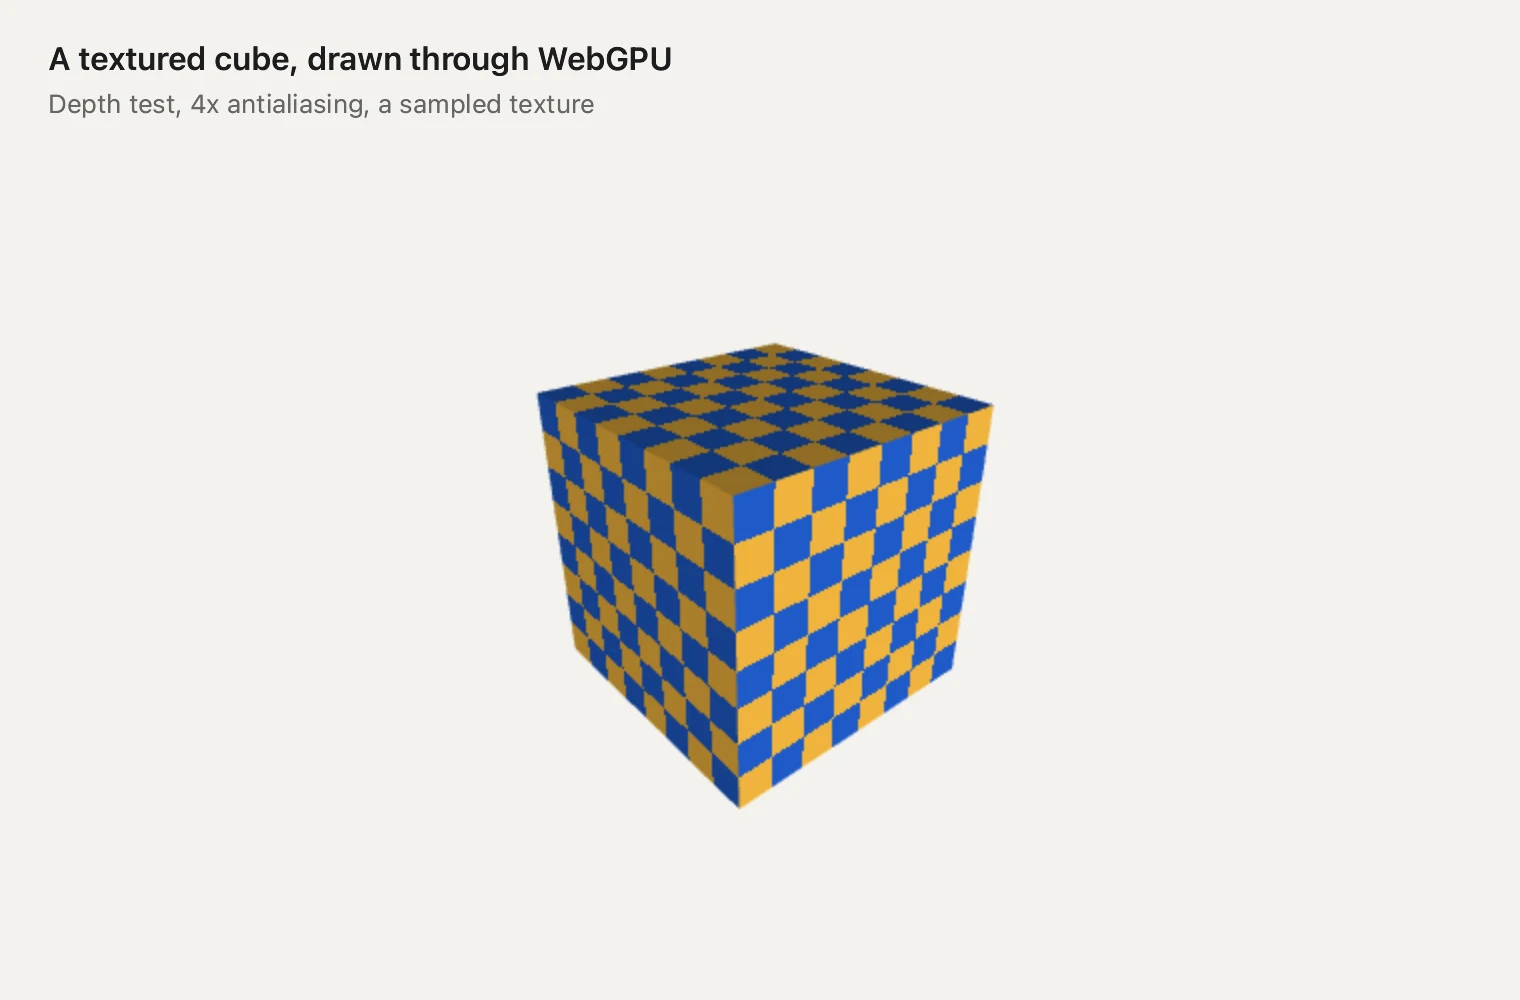
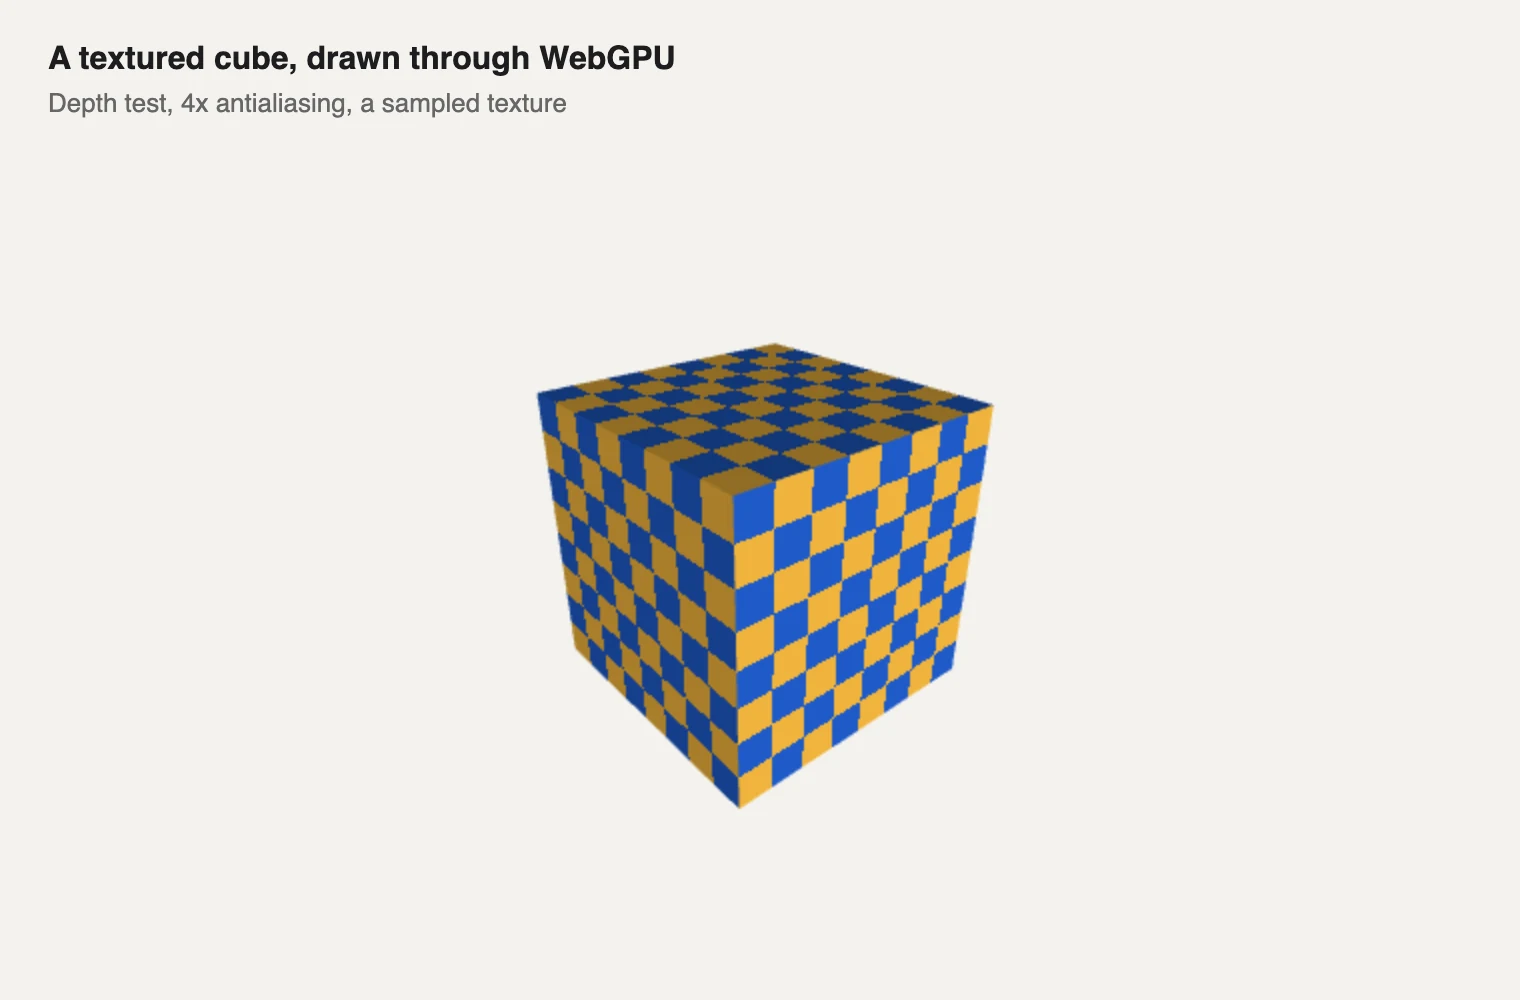
WebGPU is the modern way for a page to use the graphics card, for drawing and for computing. We built it on our own binding, in three layers: the page's objects and checks, a plain-data wire between them, and the GPU library behind it. To judge it we ran the official conformance suite through the real app and counted what happened rather than what we hoped. Of the cases it could run, 96.3% of the validation tests and 95.0% of the operation tests pass. A test cube with depth, 4x antialiasing and a texture matches the reference browser on all 160,000 pixels, and a triangle on all 76,800. A spinning cube runs at about 30% of a core, and four public samples run. There are honest gaps: workers, external textures from video, and frames still pass through the processor on the way to the screen.
Less for a site to read
The reference browser tells a page its GPU's vendor and family, and a list of optional features that varies by machine. Together those are a good fingerprint, and a GPU clock adds a way to measure what else the machine is doing. We give every machine one identity: the same name, the same limits, no optional features, and no clock. A page that needs a feature the identity does not offer will not get it, and that is the trade we chose. The same care went into memory: every allocation is charged before it happens, and objects a page lets go of are really freed.
Pixels that are not yours to read
While wiring up texture uploads we noticed that the flag we thought guarded canvas reads only tracked fingerprinting, and nothing tracked which site an image came from. So we tried it in the real app: a page on one address drew an image from another and read its pixels back. A browser must never allow that: a picture meant only for you could be read by any page you visit. Now every image carries a verdict from the moment it arrives, and an image with no verdict counts as another site's. You still see cross-origin images on a canvas as normal; the page just cannot read them back, the same rule the standard sets.
What the test suite found
The best thing a conformance suite did for us was crash. Running it through the real app, the browser died in the Apple graphics driver, and the cause was one pipeline setting that the GPU library leaves unchecked. Then a WebGL suite run showed that a nested shader ended the process, and a look at the same code turned up something worse in plain JavaScript: new ArrayBuffer(1e20) panicked the engine. All of these had been reachable by any page, and the last two were in earlier releases. Each now has a check before the work happens and a law in the test gate, and a sweep of 21 hostile sizes across the page APIs no longer finds a crash.